

What is Predictive Analytics?
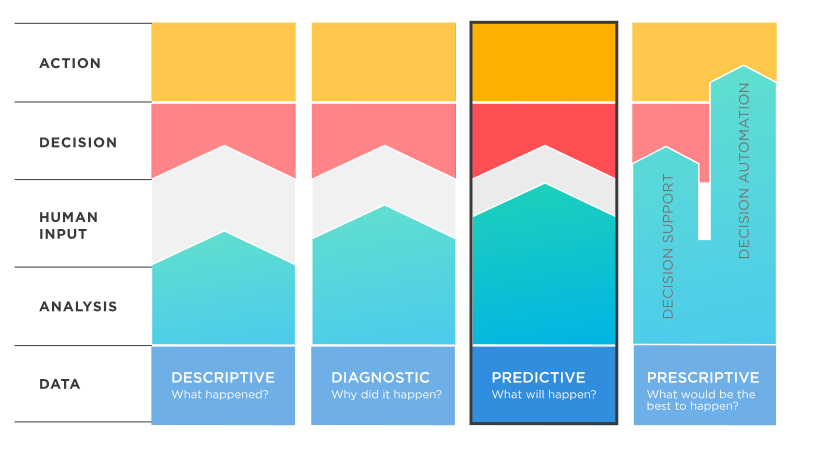
Predictive analytics is a data-driven analytical approach used to forecast future outcomes or trends based on historical and current data. It involves the application of statistical algorithms, machine learning techniques, and data mining methods to analyze data patterns, identify relationships, and make predictions. By leveraging historical data and extracting valuable insights, Predictive analytics empowers organizations to make informed decisions, optimize processes, and mitigate risks.
Key Concepts of Predictive Analytics
Predictive analytics relies on some fundamental concepts that serve as its building blocks. These concepts are essential to understanding how it works and why it is a valuable tool in various fields. Here are some of the key concepts associated with predictive analytics:
Predictive Modeling
Predictive modeling stands as the central component of predictive analytics. It revolves around using historical data to construct mathematical and statistical models, which, in turn, assist in forecasting future events or trends.
These models can vary in complexity, from basic linear regressions, which identify straightforward relationships in data, to more intricate machine learning algorithms capable of handling diverse data patterns.
The essence of predictive modeling lies in its ability to identify and quantify patterns within historical data. Closely examining the patterns in data helps identify the significant variables and their relationships that affect the predicted outcome. This analytical exercise enables organizations to leverage data effectively, anticipate future trends, refine their strategies, and make well-informed decisions that strengthen their competitive position.
Data Mining
Data mining involves uncovering concealed patterns, connections, and valuable insights concealed within extensive datasets. In predictive analytics, data mining techniques are indispensable tools for extracting valuable information from data, forming the basis for constructing predictive models.
At its core, data mining acts as a digital detective, meticulously scrutinizing vast data pools to extract valuable information. This information can include trends, correlations, or previously unnoticed relationships within the data. By identifying these hidden gems, data mining equips organizations with the means to create more accurate predictive models, enhancing their ability to foresee future events and make informed decisions.
Machine Learning
Machine learning is a specialized area in the vast artificial intelligence (AI) field that focuses on creating algorithms. These algorithms enable computers to learn from data and make predictions or decisions autonomously. In the context of predictive analytics, machine learning plays a pivotal role by harnessing the power of these algorithms to enhance the accuracy of predictions.
Machine learning doesn't follow rigid, pre-programmed rules; instead, it learns from patterns and examples within data. This ability to learn empowers machines to become better at making predictions as they encounter more information. It's similar to teaching a computer to recognize handwriting or predict whether an email is spam.
In predictive analytics, machine learning algorithms analyze historical data, uncover patterns, and use this knowledge to predict future events or outcomes. The algorithms help organizations make more informed decisions and anticipate trends with greater precision by continuously refining their predictions as they encounter new data.
Regression Analysis
Regression analysis is a statistical technique used in predictive analytics to understand how one or more independent variables relate to a dependent variable. Its primary purpose is to measure the impact of independent variables on the predicted outcome.
- Independent Variables: These factors or variables can influence the outcome we want to predict. For example, if we're predicting someone's salary, independent variables could include their years of experience, education level, and job title.
- Dependent Variable: This is the outcome we aim to predict, such as the person's salary.
Regression analysis helps us quantify the relationship between the independent and dependent variables. It calculates how changes in each independent variable affect the dependent variable. For instance, it can tell us how much a one-year increase in experience contributes to a change in salary.
By using regression analysis in predictive analytics, organizations gain a precise understanding of the impact of different factors on the outcomes they want to predict. This knowledge allows them to make more accurate predictions and informed decisions based on data-driven insights.
{{cta-1}}
The Predictive Analytics Process
Predictive analytics is a structured process that involves several sequential steps, each with a specific purpose. Understanding this process is crucial for effectively harnessing the power of data to make informed predictions and decisions. The predictive analytics process typically unfolds as follows:
Data Collection
Data collection serves as the fundamental starting point in predictive analytics. During this phase, the primary objective is gathering relevant data from various sources, including databases, surveys, online sources, or other information repositories. This collected data forms the bedrock upon which predictive models are constructed.
Here's a closer look at the key aspects of this step:
Source Diversity
Data can be sourced from many places within and outside an organization. It may encompass customer records, financial transactions, sensor readings, social media interactions, or any other pertinent information that holds insights for the predictive task. The diversity of data sources allows for a holistic understanding of the factors influencing the prediction.
Foundation for Models
The data collected during this phase is not merely a collection of numbers; it represents the real-world phenomena or behaviors that we seek to understand and predict. This data becomes the raw material from which predictive models are crafted. The quality and richness of the data directly impact the accuracy and reliability of the subsequent predictions.
Quality and Quantity
Data quality is paramount. It involves ensuring that the data is accurate, complete, and free from errors or inconsistencies. The quantity of data also matters – having sufficient data is crucial for building robust predictive models. Inadequate or poor-quality data can lead to unreliable predictions.
Data Preprocessing
Following data collection, the next crucial step in predictive analytics is data preprocessing. This phase involves getting the collected data into a clean, consistent, and usable form for analysis. The main objectives are to handle missing values, address outliers, and standardize data formats. This ensures that the data is reliable, making accurate predictions possible.
Here are the main tasks in data preprocessing:
- Handling Missing Values: Real-world data often has gaps or missing values. Data preprocessing involves strategies to fill in these gaps or remove incomplete records so that analysis isn't compromised.
- Outlier Management: Outliers are extreme data points that can skew analysis results. Data preprocessing identifies and deals with outliers by removing them or modifying their impact.
- Standardizing Data: Data can come in various formats and units. Standardizing data formats, such as ensuring all measurements use the same unit, simplifies analysis and allows for meaningful comparisons.
- Normalization and Scaling: Sometimes, data must be transformed to fit a standard scale. Normalization and scaling adjust numerical variables to a consistent range, ensuring that variables with different scales don't dominate the analysis.
- Categorical Variable Encoding: Datasets often contain categorical variables like "yes/no" or "red/blue/green." Data preprocessing includes techniques for converting these into numerical values compatible with analytical models.
Model Building
Model building is the heart of predictive analytics, where the process transitions from data preparation to making predictions. Mathematical and statistical models are crafted using the carefully prepared data in this phase.
These models can span a wide spectrum, ranging from straightforward linear regressions to more intricate machine-learning algorithms. The selection of the most suitable model hinges on the nature of the data and the specific predictive goal.
Here's a closer look at what happens during model building:
Crafting Predictive Models
Predictive models are like mathematical tools that can discern patterns and relationships within data. They are designed to capture the underlying structure of the data, allowing them to make informed predictions. The models use the patterns identified during data analysis to understand how different variables influence predicted outcomes.
Model Diversity
Predictive analytics offers a toolkit of various modeling techniques. Simple models like linear regressions are suitable when the relationship between variables is relatively straightforward.
On the other hand, complex machine learning algorithms like decision trees or neural networks can handle intricate data patterns and nonlinear relationships. The model choice depends on the problem's complexity and the available data.
Customization
Model building involves customizing the selected model to fit the specific problem. This might include fine-tuning parameters, defining input variables, and determining the target variable. The goal is to make the model's predictions as accurate as possible.
Training the Model
Once the model is set up, it's "trained" using historical data. During training, the model learns from the patterns and relationships within the data, adapting itself to predict future outcomes.
Model Evaluation
Once predictive models are constructed, model evaluation is the next critical step in the predictive analytics process. This phase is akin to quality control, where the effectiveness and reliability of the models are rigorously assessed.
Model evaluation involves using specific metrics and techniques to measure how well the model's predictions align with real-world data. Common evaluation metrics include accuracy, precision, recall, and the F1 score. This evaluation is vital for determining whether the model suits the intended predictive task and if any adjustments or improvements are necessary.
Here's a closer look at what occurs during model evaluation:
Performance Metrics
Various performance metrics are employed to gauge the performance of a predictive model. These metrics provide quantitative measures of how well the model is performing. Here are a few common ones:
- Accuracy: Measures the proportion of correct predictions made by the model.
- Precision: Indicates how many of the positive predictions made by the model were correct.
- Recall: Measures the proportion of actual positive cases the model correctly predicted.
- F1-score: Combines precision and recall into a single metric, providing a balanced assessment of the model's performance.
Comparison to Real Data
During model evaluation, the model's predictions are compared to real-world data. This involves testing the model with a separate dataset (not used during training) to assess its ability to make accurate predictions on unseen data.
Adjustments and Improvements
Based on the evaluation results, adjustments to the model may be necessary. This could involve modifying the model's parameters, altering its architecture, or even selecting a different modeling approach if the current one doesn't perform well.
Iteration
Model evaluation often leads to an iterative process. Models are refined and re-evaluated until their performance meets the desired level of accuracy and reliability.
At its core, model evaluation is a critical checkpoint in predictive analytics. It ensures that the models created are functional and effective in making accurate predictions. Organizations can fine-tune their models and make necessary improvements by using performance metrics and comparing model predictions to real-world data.
Deployment
After a predictive model has been successfully developed and evaluated, the next crucial phase in the predictive analytics process is deployment. Deployment is where the model is implemented, becoming an integral part of an organization's operations.
This phase involves integrating the model into the systems or processes of the organization, allowing it to make real-time predictions and inform decision-making. Effective deployment ensures that the valuable predictive insights derived from the model are put into practical use to drive business improvements and optimize processes.
Here's a closer look at what occurs during model deployment:
- Integration: The developed model is integrated into the organization's existing systems or processes. This may involve incorporating it into the organization's software applications, databases, or decision-support tools.
- Real-Time Predictions: Once deployed, the model operates in real-time, making predictions on new data as it becomes available. For example, a predictive model for fraud detection could analyze every incoming transaction for potential fraud.
- Automation: Automation is a key aspect of deployment. The predictive model works autonomously, continuously analyzing and making predictions without manual intervention.
- Informed Decision-Making: The predictions generated by the model are used to inform decision-making processes within the organization. For instance, a model for inventory management might predict when certain products are likely to run out of stock, prompting timely reorder decisions.
- Monitoring and Maintenance: Even after deployment, ongoing monitoring and maintenance are essential. This ensures that the model continues to perform accurately over time. Adjustments may be necessary if the model's performance deteriorates or data patterns change.
- Feedback Loop: Deployment often establishes a feedback loop, where the model's predictions and outcomes are continuously compared. This feedback loop helps refine the model further and improve its accuracy.
{{cta-2}}
Applications of Predictive Analytics
Predictive analytics is a versatile and powerful tool that finds applications in various industries. Here are some key domains where predictive analytics is making a significant impact:
Business and Marketing
- Customer Segmentation: Predictive analytics helps businesses segment their customer base based on behavior, preferences, and purchasing history. This allows for targeted marketing campaigns and personalized recommendations.
- Churn Prediction: Businesses can predict which customers are likely to churn (stop using their services) and take proactive measures to retain them.
- Sales Forecasting: Predictive models can forecast future sales trends, enabling better inventory management and strategies.
Healthcare
- Disease Diagnosis: Predictive analytics aids in early diagnosis by analyzing patient data, such as symptoms and medical history, to identify potential health issues.
- Patient Readmission: Hospitals use predictive models to predict which patients are at a higher risk of readmission, helping allocate resources more effectively.
- Drug Discovery: Pharmaceutical companies employ predictive analytics to expedite drug discovery processes and identify potential candidates for further research.
Finance
- Credit Scoring: Predictive models assess an individual's creditworthiness, enabling banks and lenders to make informed lending decisions.
- Fraud Detection: Financial institutions use predictive analytics to detect real-time fraudulent activities, preventing unauthorized transactions.
- Stock Market Predictions: Traders and investors employ predictive models to forecast stock prices and make investment decisions.
Manufacturing
- Predictive Maintenance: Manufacturers use predictive analytics to anticipate when equipment or machinery might fail, enabling timely maintenance and reducing downtime.
- Quality Control: Predictive models help identify product defects and quality issues during manufacturing.
- Supply Chain Optimization: Predictive analytics optimizes supply chain operations by forecasting demand, managing inventory, and improving logistics.
Sports
- Player Performance Analysis: Sports teams use predictive analytics to assess player performance, injury risk, and strategic decisions during games.
- Fan Engagement: Predictive analytics is employed in sports marketing to understand fan behavior and tailor engagement strategies.
- Recruitment and Drafting: Sports organizations use predictive models to evaluate potential recruits and draft picks based on their predicted performance.
These are just a few examples of how predictive analytics revolutionizes decision-making and operations across various industries. Its ability to turn data into actionable insights makes it valuable in optimizing processes, enhancing customer experiences, and driving innovation.
Final Thoughts
Predictive analytics is a transformative approach that empowers organizations across various industries to harness the power of data for making informed decisions, optimizing processes, and improving outcomes. This dynamic field, built upon data collection, preprocessing, model building, evaluation, and deployment, continues to evolve with the integration of cutting-edge tools and emerging technologies.
Ready to give it a spin?
Start your 30-day trial now.
Try Jaspersoft - Free Trial
Efficiently design, embed, and distribute reports and dashboards at scale with Jaspersoft.
Build versus Buy: An In-depth Guide
This whitepaper provides a framework for the decision-making process and critical trade-offs between building or buying an embedded BI and reporting tool.
Interactive demo: Bikeshare Embedded BI, supported by Jaspersoft
Experience how to turn data into valuable insights that you and your customers can use to make better decisions.
